Status 11 November 2026. The SupraAgent benchmark measures three things separately: whether retrieval finds the right module source, whether facts survive in very long sources, and how fast the local components run. Every run is a local diagnostic: real retrieval, admission and synthesis components over a fixture index, with deterministic extraction, no model-provider calls and no executed business actions. The numbers below are the current state of that benchmark. They are not answer correctness, not a user study and not evidence of being the best agent.
Study | Size | What it measures |
|---|---|---|
Module replay | 96 questions × 2 retrievers × 3 repeats = 576 runs | Module hit@1 and hit@4, MRR, citation markers, local runtime |
Long sources | 144 cases × 3 repeats = 432 measurements | Facts retained in prompt and answer, visible limits, safety controls, runtime per length |
Context fixtures | 9 × 5 × 3 = 135 executions | Source recall and literal fact presence per retrieval method |
Module routing: 96 questions over 1,037 documentation sections
The questions cover People, Teaching, Attema, Blogery, Store Connect, Deals, IoT Manage, Shortcuts, iAccelerator, Help Center, Templaterr and SupraAgent. Each module has four question types in German and English: actions with inputs and prerequisites, activities and status, process steps with verifiable outcomes, and support for permission errors and missing information. Examples ask how to assign a learner to a Teaching group, what to check before an IoT Manage device update, how to separate reads, changes, approval and outcome checks when publishing in Blogery, and how to diagnose a People permission error without bypassing access controls. The corpus contains 1,037 complete endpoint documentation sections; both retrievers see the same sources, and insertion order is reversed on alternate repeats.
Measure, first repeat | BM25 | Hash vectors |
|---|---|---|
Module hit@4 (a source from the requested module in the top four) | 96/96 | 74/96 |
Module hit@1 (the first listed source is from the requested module) | 77/96 | 57/96 |
MRR of the first module source | 0.891 | 0.663 |
Local p50 / p95, 288 runs | 9.982 / 13.067 ms | 81.008 / 84.447 ms |
Failed runs, lost or unresolved citations | 0 | 0 |
Hit@1 matters because readers act on the first listed source (Craswell et al., WSDM 2008). BM25 scores fields separately, with the section title weighted 2.5 against source and content (Robertson, Zaragoza and Taylor, CIKM 2004); the weight comes from a sweep plateau and places no question's module source lower than unweighted scoring does. Per-document token statistics live in a bounded cache of 20,000 entries and 64 MiB of text, with identical scores cold and warm (Robertson and Zaragoza, 2009); the one cold run took 31.067 ms. Timing is one workstation without model calls or production IO, read against the 0.1-second perceptual threshold of Card, Robertson and Mackinlay, CHI 1991, not as a service commitment. Hash vectors are deterministic lexical hashes, not a neural embedding baseline.
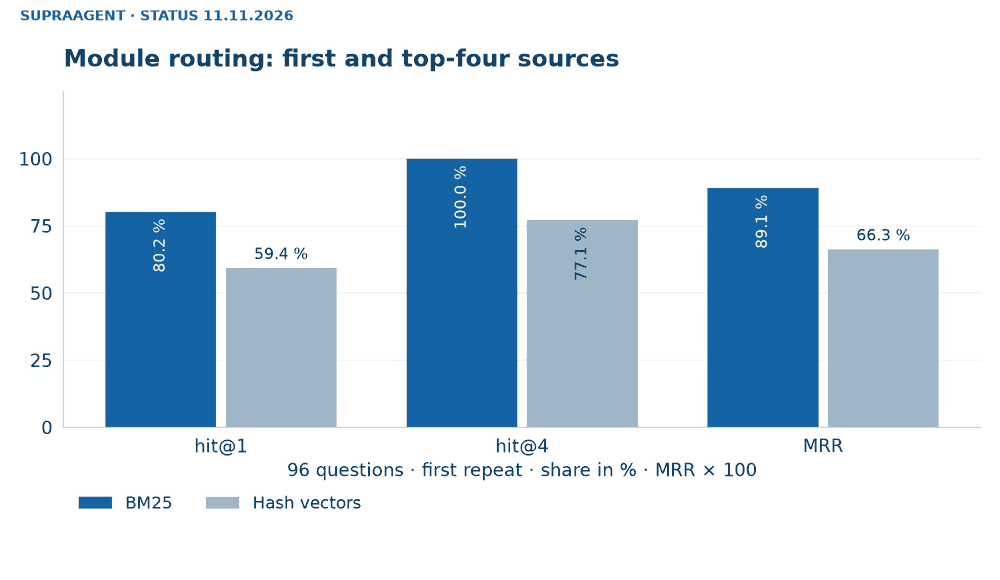
1. Module routing: first and top-four sources per retriever, 96 questions, first repeat.
BM25 by group | Hit@1 | Hit@4 |
|---|---|---|
Actions (24) | 22/24 | 24/24 |
Activities (24) | 19/24 | 24/24 |
Processes (24) | 17/24 | 24/24 |
Support (24) | 19/24 | 24/24 |
German (48) | 38/48 | 48/48 |
English (48) | 39/48 | 48/48 |
Every question type reaches its module within the top four. First-position routing is weakest for process questions and for two modules: Shortcuts places its module source first in 1 of 8 questions and Store Connect in 3 of 8, while Attema, Blogery, Deals and Help Center reach 8 of 8. Hash vectors score 0 of 8 for Help Center even in the top four. These are concrete development targets, not a ranking of language or support quality; language and question-type rows overlap and must not be added together.
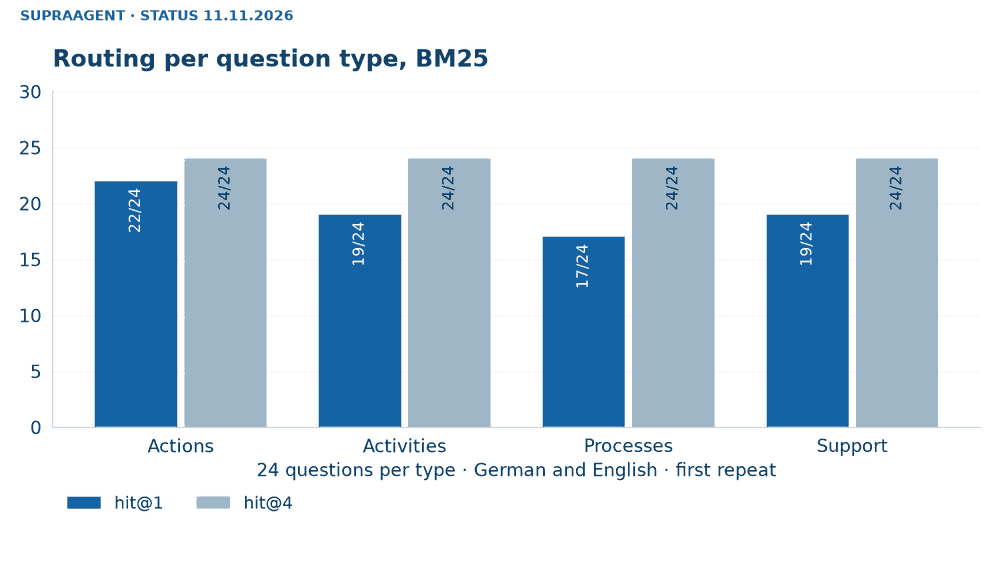
2. Routing per question type, BM25, 24 questions per type in German and English.
Long sources: 144 controlled cases up to 1,024,000 characters
The long-source study crosses six source lengths, 8,000 to 1,024,000 characters, with evidence placed at the beginning, middle and end, in German and English, as motivated by Lost in the Middle (Liu et al., TACL 2024). Four scenarios test a positive fact, an oversized negation, an injected instruction and an absent fact. Each case runs three times and is measured twice: at the provider-prompt boundary and in the deterministic answer. Lengths are Unicode characters, not model tokens, and no model comprehension is measured (Bai et al., ACL 2024).
Source length (characters) | Facts in prompt | Facts in answer | Limit notice in the answer | Prompt p50 | Answer p50 |
|---|---|---|---|---|---|
8,000 | 12/12 | 12/12 | 0/24 | 1.5 ms | 9.0 ms |
32,000 | 12/12 | 12/12 | 0/24 | 4.7 ms | 30.9 ms |
128,000 | 12/12 | 12/12 | 0/24 | 17.3 ms | 113.1 ms |
256,000 | 12/12 | 12/12 | 24/24 | 27.4 ms | 201.7 ms |
512,000 | 12/12 | 12/12 | 24/24 | 31.7 ms | 235.6 ms |
1,024,000 | 12/12 | 12/12 | 24/24 | 38.1 ms | 295.7 ms |
The complete scan of a source is bounded at 200,000 characters and 4,096 source units. Beyond that bound the packer segments at most sixteen windows of 8,192 characters on either side of whole-word matches of the question terms, rarest term first, discards every window-edge sentence and carries bracket scope across the gaps. Each bound that is reached is a named omission in the provider prompt, and the deterministic answer opens with one localized sentence saying that the source was only partially read, following guidelines G2 and G11 of Amershi et al., CHI 2019. The notice carries no citation marker and never appears for sources within the bound. The attribution checker and the grounding audit read the same question-anchored windows, so a number cited from the end of a long source is verified against that source rather than rejected. Correctness and citation support remain separate questions (Gao et al., EMNLP 2023).
Control (144 cases × 3 repeats) | Prompt | Answer |
|---|---|---|
Oversized negation withheld, no detached positive predicate | 36/36 | 36/36 |
Injected instruction projected | 0 | 0 |
Absent fact reported as present | 0 | 0 |
Limit notice for a source within the 200,000-character bound | 0 | 0 |
These bounded controls do not establish general attack resistance. The answer path grows with length because the packer, the attribution checker and the grounding audit each scan the anchored windows; at 1,024,000 characters the deterministic answer takes about 0.3 seconds on the test workstation and returns the fact.
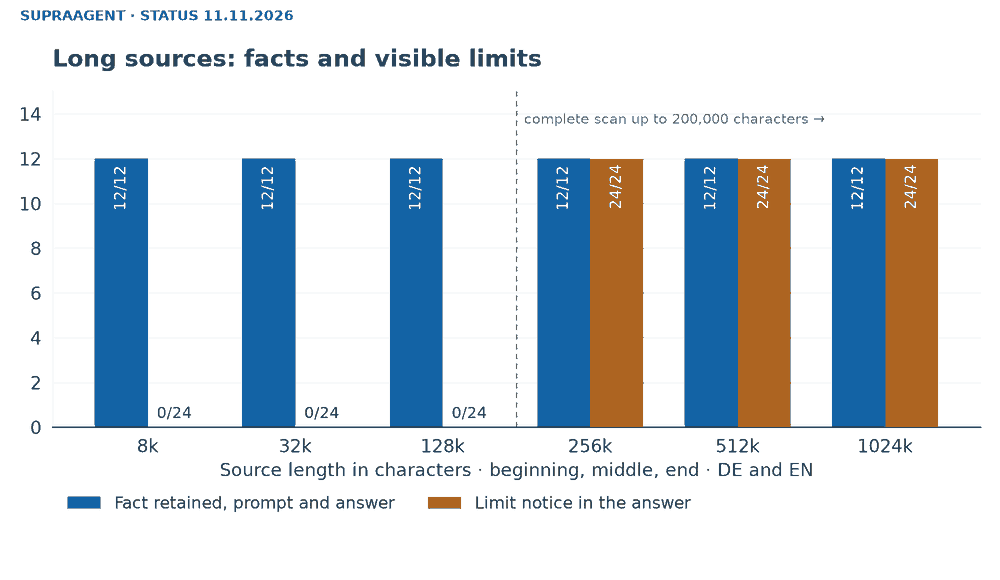
3. Long sources: facts retained and limit notices per length, beginning, middle and end, German and English.
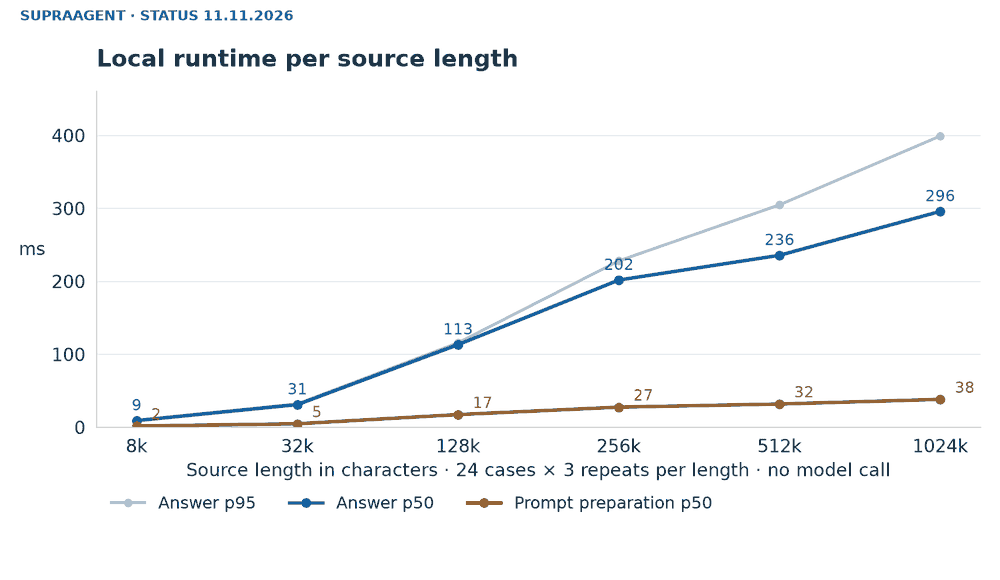
4. Local runtime per source length, 24 cases × 3 repeats per length, no model call or production IO.
Context fixtures: source recall per retrieval method
Method | Source recall (5 cases) | Fact presence (4 cases) |
|---|---|---|
BM25 | 65% | 50% |
Hash vectors | 65% | 50% |
Graph, 1 hop | 90% | 75% |
Graph, 3 hops | 100% | 100% |
Hybrid graph | 100% | 100% |
Three graph hops recover every expected source and reference fact in these small authored fixtures. This is an integration diagnostic: literal fact presence does not establish entailment, and synthetic benchmark.invalid addresses are test identifiers.
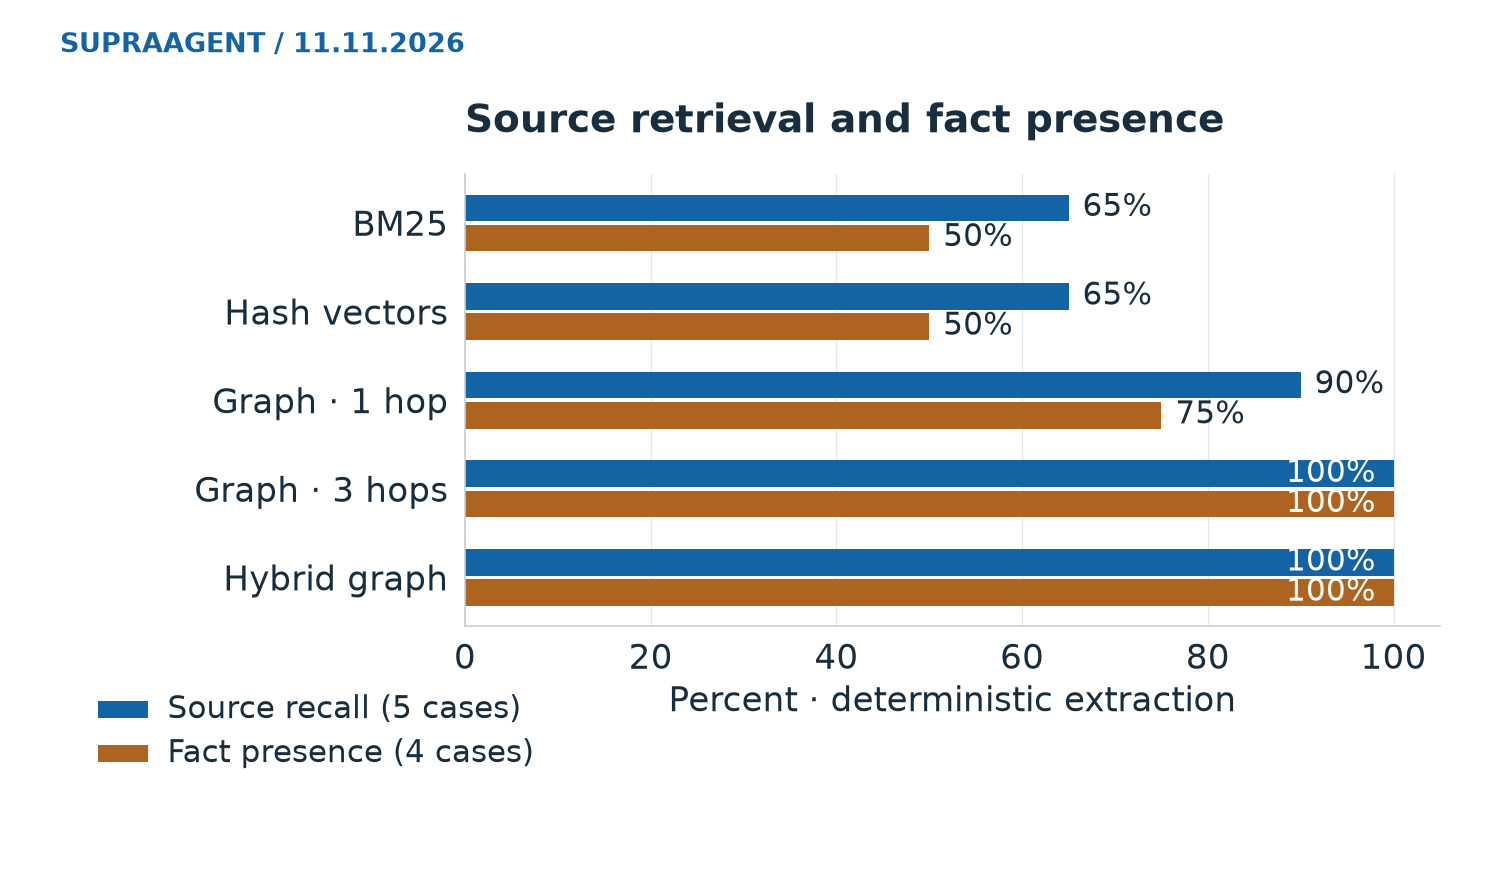
5. Context fixtures: source recall over five annotated cases and literal fact presence over four cases. Does not measure semantic accuracy.
What source links establish
Every numeric source marker in the module replay resolves to an admitted source ID, with zero lost or unresolved citations across all 576 runs. Source-ID resolution is structural, not semantic citation support. Answer correctness, translation quality, support usefulness and process success remain unmeasured without independent assessment.
Peer-reviewed methodology
The design follows peer-reviewed work; every DOI was verified through Crossref. The papers guide the measurements and do not certify SupraAgent.
Robertson, Zaragoza and Taylor (CIKM 2004), Simple BM25 extension to multiple weighted fields: field weighting for the section title.
Robertson and Zaragoza (2009), The Probabilistic Relevance Framework: BM25 and Beyond: the scoring model and its per-document statistics.
Craswell et al. (WSDM 2008), An experimental comparison of click position-bias models: why the first listed source is measured separately.
Card, Robertson and Mackinlay (CHI 1991), The information visualizer: the 0.1-second perceptual threshold used to read local runtime.
Liu et al. (TACL 2024), Lost in the Middle: evidence position in long contexts.
Bai et al. (ACL 2024), LongBench: why character-length retention is not model comprehension.
Gao et al. (EMNLP 2023), ALCE: answer quality and citation quality are separate.
Amershi et al. (CHI 2019), Guidelines for Human-AI Interaction: making capability limits visible in the answer.
Lewis et al. (NeurIPS 2020), Retrieval-Augmented Generation: retrieval and generation are reported as separate stages.
Yao et al. (ICLR 2025), tau-bench: process performance requires outcome checks against the resulting state, which this benchmark does not run.
Evidence, reproduction and limits
Reports, archived sources, raw answers, figures and reproduction commands are in the evidence bundle (GitHub access required). The bundle freezes source hashes before and after each run and is fingerprinted with SHA-256; 1,133 focused tests pass on the measured code. Repeats and translation pairs are dependent, so no significance claim is made.
A product-level quality claim would additionally require independently assessed answers and citation support, fresh tenant-domain holdout questions, human evaluation of the user experience, production latency under load, and isolated workflow runs with verified before/after state. Until then this benchmark supports specific retrieval, retention and regression diagnostics. It does not establish general accuracy, successful live workflows or superiority to other agents.